Liquid Clustering vs Z-ORDER vs Partitioning: Which to Choose
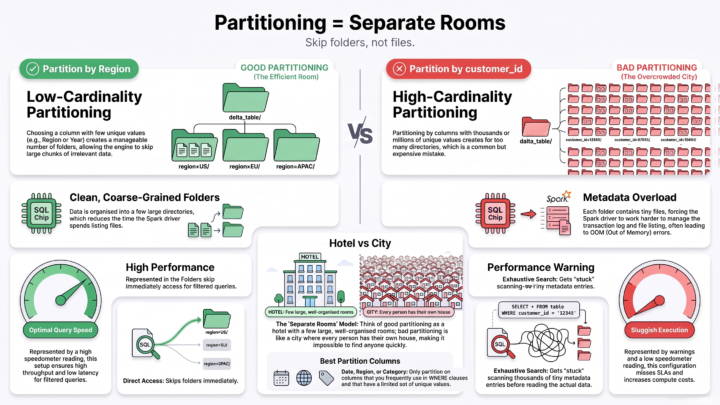
Three ways to lay out a Delta table so queries read less data — and the senior skill isn't picking the newest one, it's knowing when NOT to switch. Explained with a bookstore.
Read MoreThree ways to lay out a Delta table so queries read less data — and the senior skill isn't picking the newest one, it's knowing when NOT to switch. Explained with a bookstore.
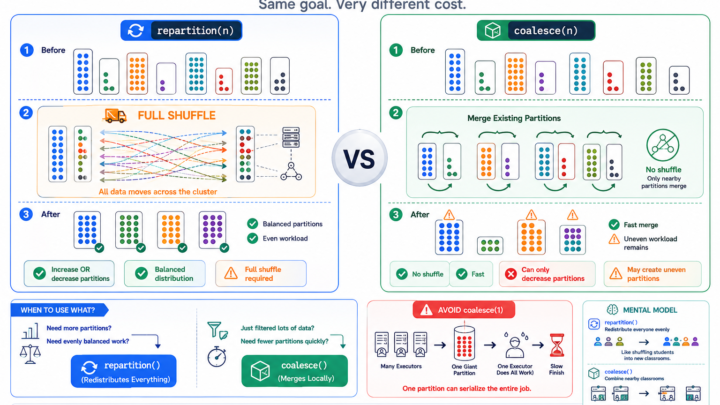
Read MoreBoth change the number of partitions — but one does a full shuffle and one doesn't, and that single difference decides your performance. Plus the coalesce(1) trap everyone falls into.
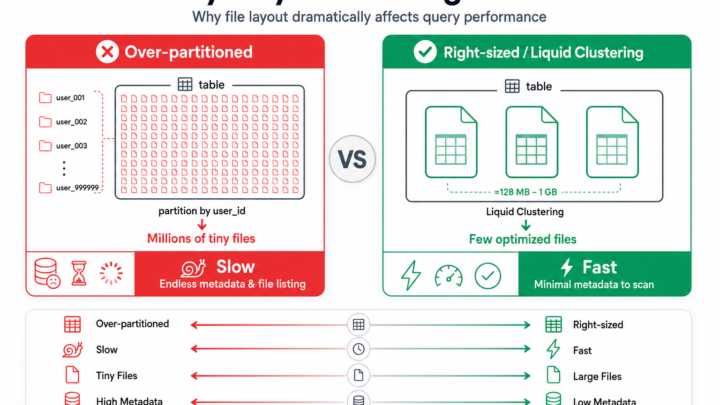
Read MorePartitioning by the wrong column shatters your table into millions of tiny files and grinds queries to a halt. Here's how to right-size it — and why liquid clustering is usually the better answer.
Read MoreNo error, just wrong data: partition by a column with empty strings and Spark reads them back as null. Here's exactly why — and how to keep the values distinct.
Read More