The Small Files Problem in Spark: How to Detect and Fix It
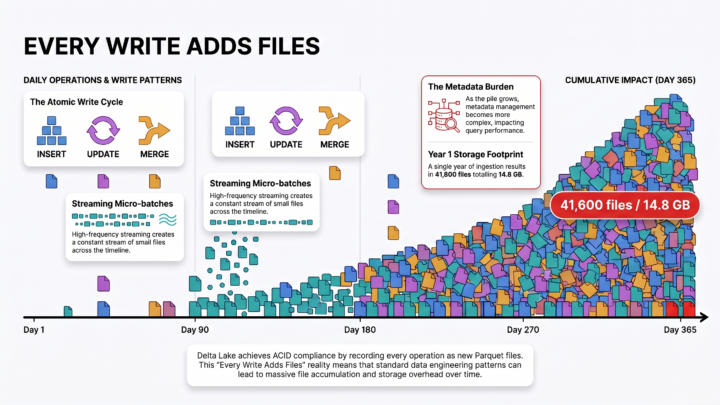
41,600 files holding 14.8 GB took 34 minutes just to scan. Here is what causes the small files problem, the exact numbers that reveal it in the Spark UI, and four ways to fix it.
Read More41,600 files holding 14.8 GB took 34 minutes just to scan. Here is what causes the small files problem, the exact numbers that reveal it in the Spark UI, and four ways to fix it.
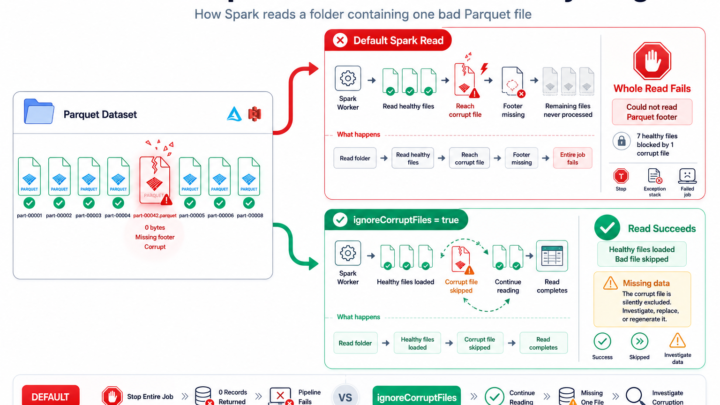
Read MoreOne bad file shouldn't take down the whole read. Here's why Parquet files corrupt, how to skip past them to get your data now, and how to find and fix the real culprit.
Read MoreNo error, just wrong data: partition by a column with empty strings and Spark reads them back as null. Here's exactly why — and how to keep the values distinct.
Read More"Failed to merge incompatible data types" and "Parquet column cannot be converted" both mean your files disagree on a column's type. Here's how to fix compatible and incompatible cases.
Read MoreThe error almost always means one thing: Spark found no data files at the path. Here's the 30-second fix, the real root causes, and how to stop it happening again.
Read MoreThe file format under your data quietly decides how fast and cheap your queries are. Here's what each one is for — and why Parquet often wins for analytics.
Read More