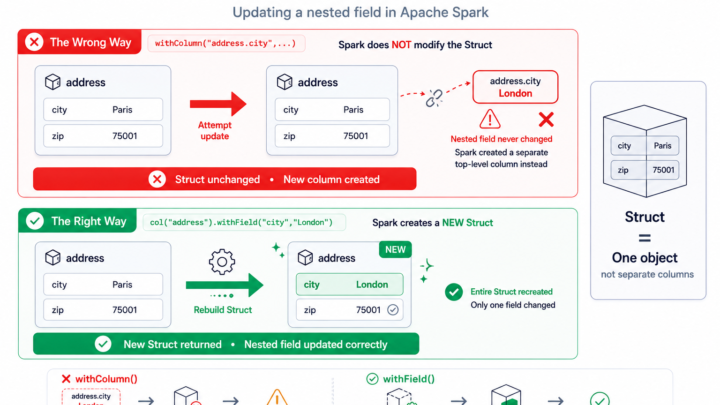
How to Update Nested (Struct) Columns in PySpark & Spark
withColumn("address.city", …) doesn't update the nested field — it quietly creates a weird new one. Here's how to actually update, add, and drop fields inside a struct.
Read MorewithColumn("address.city", …) doesn't update the nested field — it quietly creates a weird new one. Here's how to actually update, add, and drop fields inside a struct.
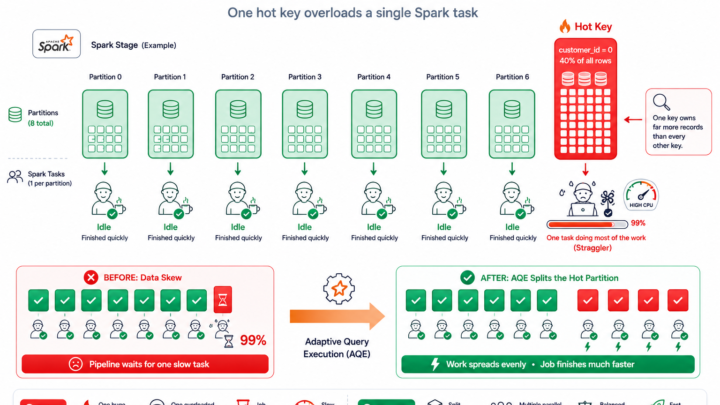
Read MoreYour job is "99% done" for an hour because one task got all the data. That's skew. Here's how to fix it with AQE, broadcast joins, skew hints, and salting.
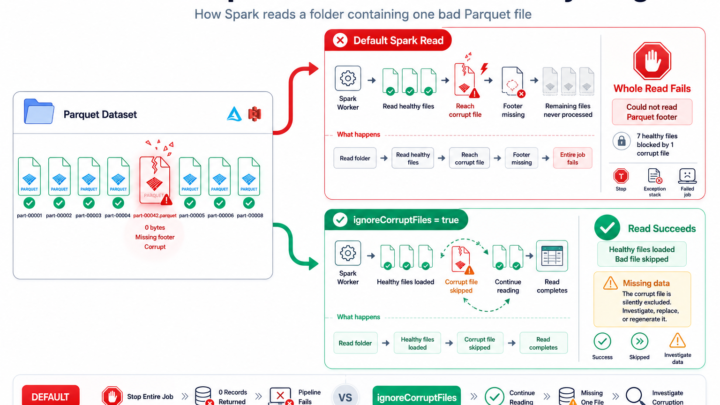
Read MoreOne bad file shouldn't take down the whole read. Here's why Parquet files corrupt, how to skip past them to get your data now, and how to find and fix the real culprit.
Read MoreTwo jobs wrote the same Delta table and one blew up. Here's what optimistic concurrency is really doing, and how to fix conflicts with partition filters, retries, and row-level concurrency.
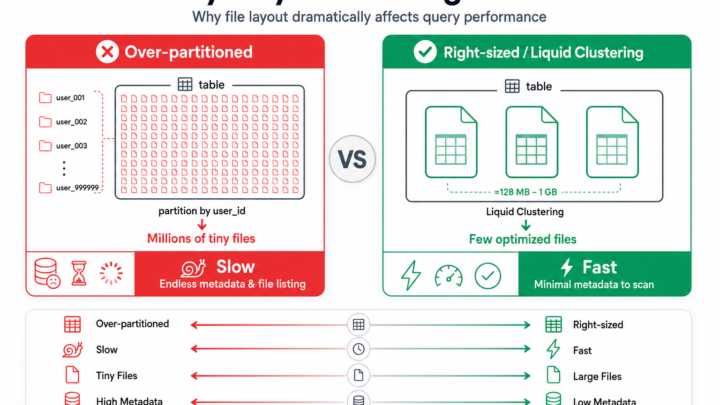
Read MorePartitioning by the wrong column shatters your table into millions of tiny files and grinds queries to a halt. Here's how to right-size it — and why liquid clustering is usually the better answer.
Read MoreNo error, just wrong data: partition by a column with empty strings and Spark reads them back as null. Here's exactly why — and how to keep the values distinct.
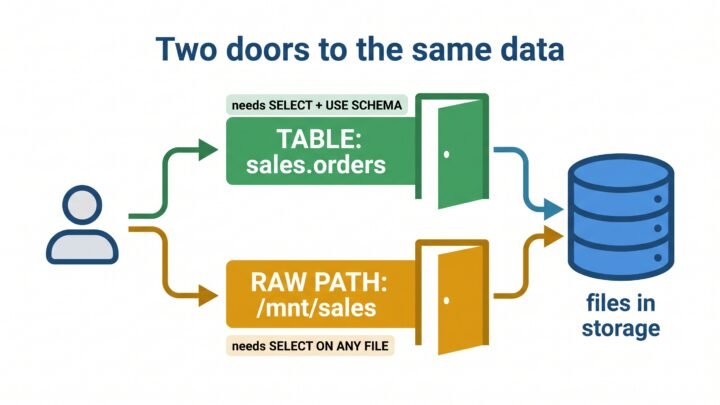
Read MoreYou're reading data by file path on a Table-ACL cluster. The blunt fix is dangerous — here's what the error means and the scoped, safe way to grant file access.
Read MoreGranting SELECT isn't enough. Databricks needs USAGE (USE SCHEMA) on the database too — because permissions are a hierarchy. Here's how to grant the right privileges.
Read More